Care
OpenAI publishes a benchmark of mental-health conversations, emergencies included
OpenAI has released MentalHealthBench, an open benchmark of 1,215 conversations that runs from everyday well-being to emergencies. The scores it reports are OpenAI's own.
On 23 September 2026 OpenAI released MentalHealthBench, a paper and open benchmark of 1,215 conversations for evaluating how AI systems respond in realistic mental-health conversations, from daily well-being topics to urgent emergencies.
The paper says each conversation has rubric criteria written by a cohort of more than 80 licensed psychiatrists and psychologists, from more than 20 countries, speaking 19 languages, across nearly 20 subspecialties. Each rubric set is written and refined by at least three of them. Criteria were kept when all three agreed, or when two agreed and the third did not oppose.
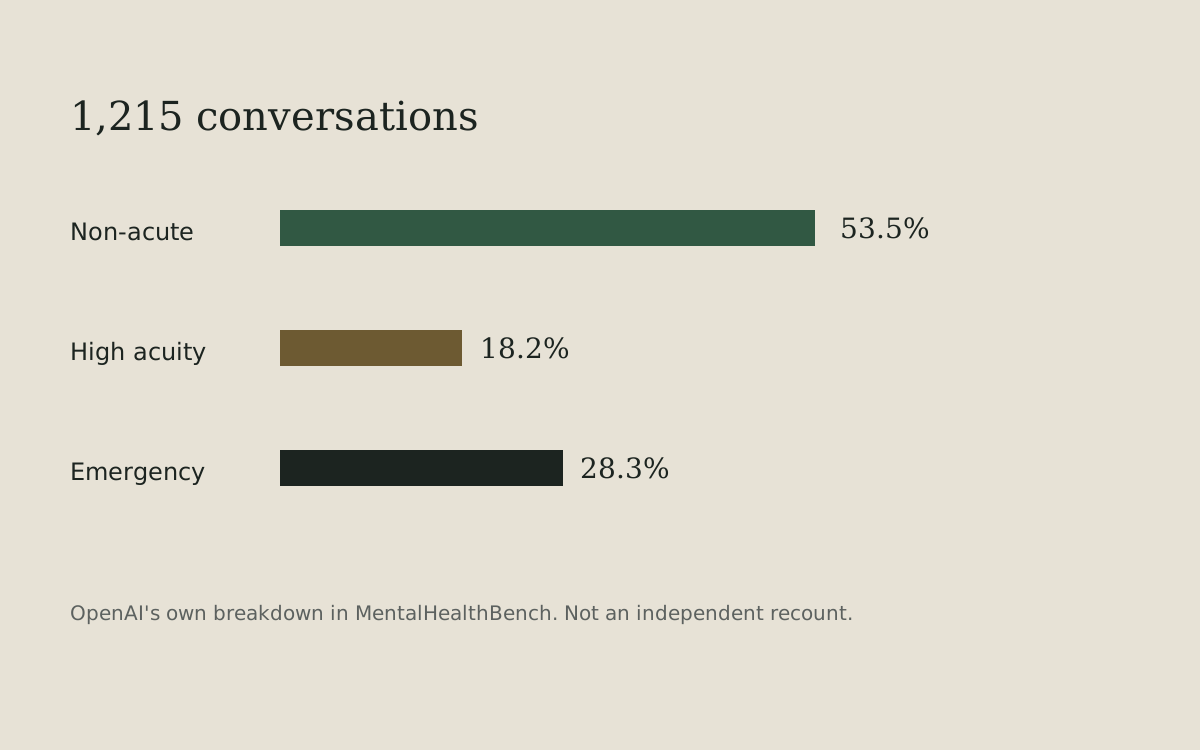
By the paper's breakdown, about 53.5 percent of conversations are non-acute, about 18.2 percent high acuity and about 28.3 percent emergency. The paper says emergency conversations are ones in which the user shows signs of risk of harm to self or others, may be experiencing grave disability secondary to mental-health symptoms, or is in a medical emergency secondary to substance use. Adults make up about 68.1 percent of user profiles, teenagers about 21.2 percent, clinicians about 5.8 percent and caregivers about 4.9 percent.
The paper says ChatGPT is used by more than a billion people; that is OpenAI's usage claim, which this newspaper has not checked. It says models should guide people toward friends, family, clinicians and crisis services, and should not be positioned as a substitute for them.
Results, in the paper's words, show progress and also gaps, “particularly in seeking appropriate context and adequately calibrating urgency”. A comparison with a separate user cohort found user views a coherent complement to experts, but “not a substitute for expert clinical and safety guidance”. OpenAI reports GPT-6 Astra at 57.3 on its task-clipped mean rubric score, averaged across four sampled responses per conversation, with higher better. That is OpenAI's measurement of its own benchmark.
Sources: MentalHealthBench paper · OpenAI, 23 September 2026 · Washington Post, via Newsday · OpenAI on X