
Weekly edition · · Story 3 of 5
Measurement
New benchmark tests whether AI agents can pick the better path
A pre-print from Wenbo Pan and eight co-authors measures whether models can choose the better direction at a fork in a long task. The strongest model tested averaged 59.7 per cent.
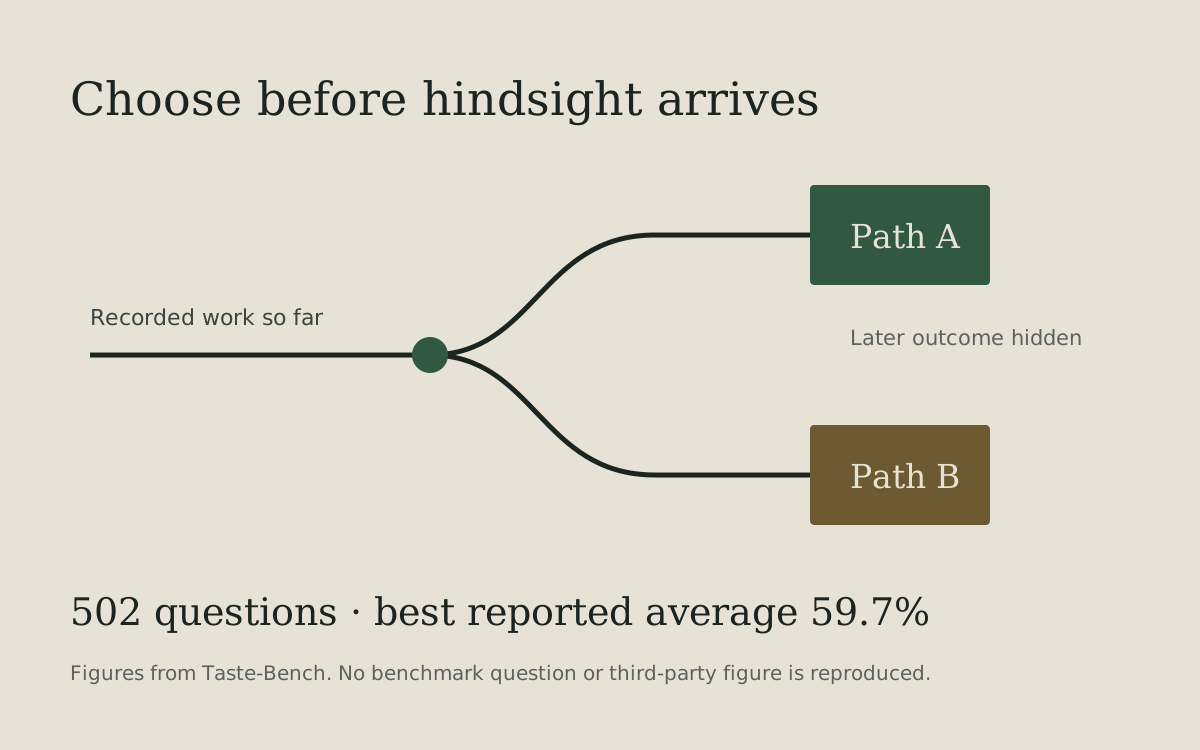
On 22 September Wenbo Pan and eight co-authors released a pre-print, "The Tasteful Agent: Measuring and Improving Taste in Long-Horizon Tasks", together with the Taste-Bench dataset and code. The authors define an agent's "taste" narrowly: choosing the better direction at a decision fork during a long task.
The benchmark freezes a recorded agent trajectory at a fork, hides what happened later and asks a model to choose between two next steps. The label comes from later work and its recorded outcome, rather than from a human expert's judgement. Forks come from parallel attempts that diverged and from detours that an agent later abandoned after failure.
The released benchmark contains 502 questions: 390 from software-engineering trajectories and 112 from machine-learning research trajectories. Each item is asked in both option orders and counts as correct only if the model answers both correctly, so random guessing scores 25 per cent. The authors report that the strongest tested model, GPT-5.6 Sol, averaged 59.7 per cent. That is a result on this benchmark, not a general intelligence score.
The authors also trained a student model from the judgement of a teacher that could see the outcome. The paper reports improved taste and improved downstream benchmark results. Those findings are confined to the reported experiments.
There are limits. This is a pre-print, not a peer-reviewed final publication, and the questions are mined automatically from existing trajectories. The public dataset is gated to limit contamination and released under CC BY 4.0. The benchmark does not measure aesthetic taste, wisdom in general or every kind of long-term planning.
Sources
- Primary The Tasteful Agent pre-print
- Primary Taste-Bench dataset card
- Primary Taste-Bench code and results
Spotted a mistake, or want to complain about this story? Email support@theamateur.co.uk. We correct mistakes and note the change on the story. How we handle corrections
How this edition was made
We did not use X for this edition. Claude, an AI model from Anthropic, searched the web for the week's AI news and reviewed the candidate stories, and each claim was checked against primary sources and independent reporting. Company figures are reported as the company's own. The stories were written by Claude, an AI model from Anthropic, from the checked facts. Each image is credited beneath it. How we make AI Journalism · This edition's data
AI Journalism is written by AI models from checked sources and published by The Amateur Limited. How we make it