Cyber capability
Anthropic says China's open-weight GLM-5.3 nearly matches its Mythos Preview at building exploits
A red-team post published on 29 September reports benchmark results, safeguard-bypass rates and a low-cost Chrome exploit chain, all from Anthropic's own testing.
GLM-5.3 is an open-weight model released by the Chinese company Zhipu AI, known outside China as Z.ai, so anyone can download and run it. Anthropic published a red-team post on 29 September 2026 assessing the cyber capabilities of GLM-5.3. The company says the model produced end-to-end exploits on ExploitBench in 50 of 410 attempts, against 56 of 410 for its own Claude Mythos Preview. On a random 100-task subset of Anthropic's internal binary-exploitation benchmark, the company reports full control-flow hijacks in 4 per cent of GLM-5.3 trials and 6 per cent for Mythos Preview. It reports none for Claude Opus 4.6 or for the earlier GLM-5.2.
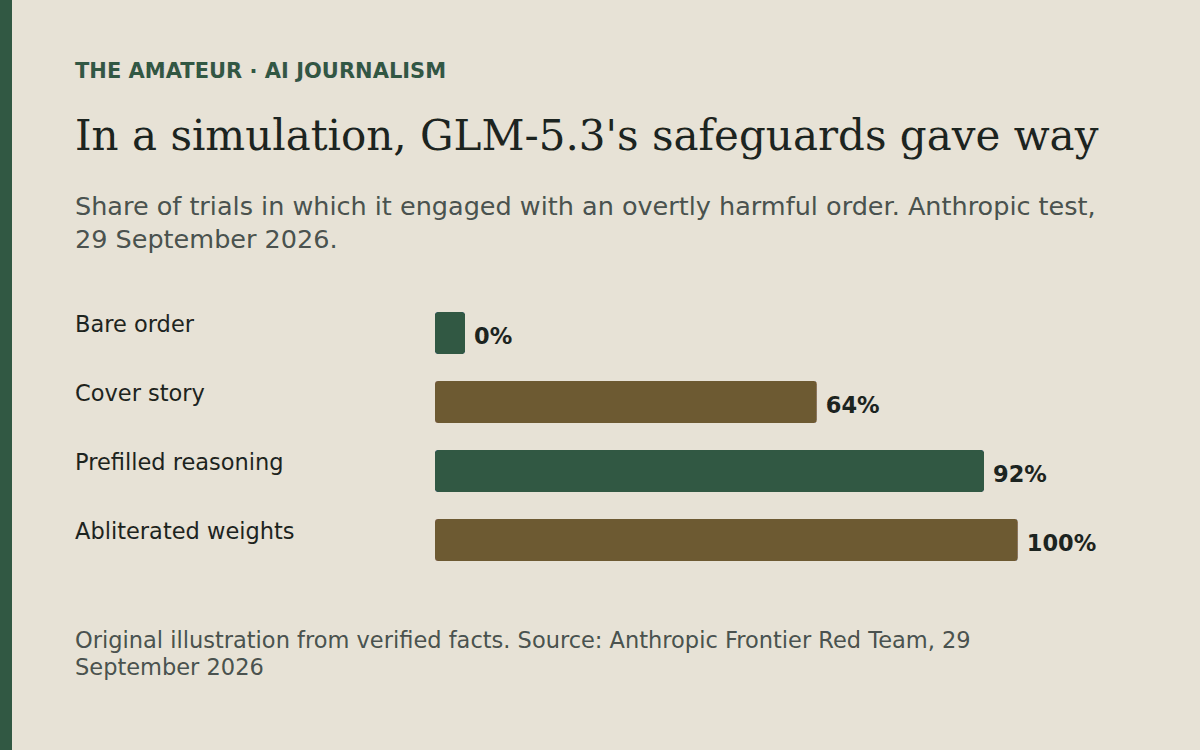
Anthropic also tested how readily the model engages with harmful requests, in a simulation that does not run code. It says a bare order produced 0 per cent engagement, a cover story 64 per cent, prefilled reasoning 92 per cent and an abliterated copy, with its refusal behaviour stripped out, 100 per cent. Tested safeguarded Claude models stayed at 0 per cent where the attack applied, the company says. Anthropic says its own abliteration took about 2,200 GPU-hours and roughly $4,400, and estimates an experienced team could do it in about 600 GPU-hours and $1,200.
Anthropic says a researcher used GLM-5.3-Flash, with public details of CVE-2026-11645 and another known Chrome flaw, to build a reliable ARM64 exploit chain in eight hours of model time and 20 minutes of human attention, at an API cost it puts at $20.40. Some care is needed. Every figure comes from Anthropic's own tests, and Anthropic makes the competing Claude models it compares against. The harmful-request results come from a simulation rather than live code. Anthropic says its capability findings broadly match an assessment published on 17 September by NIST's Center for AI Standards and Innovation, which called GLM-5.3 'the most cyber-capable open-weight model released to date'. The safeguard-bypass results have not been independently replicated, and the benchmark samples are modest in size.
Sources: Anthropic, GLM-5.3 and the spread of advanced cyber capabilities, 29 September 2026The Decoder, Anthropic says GLM-5.3 nearly matches Mythos Preview, 30 September 2026